Trust & Security
AI Privacy
How Ragently handles prompts, responses, metadata, and encrypted model requests.
Built on the Venice AI architecture
Your customers' privacy is central to how Ragently is built. Conversations are processed by default through Venice AI infrastructure, relayed over encrypted connections with prompt content never retained by Venice. Only when Venice is temporarily unavailable, or when an image uploaded in the chat is analyzed, is the request processed by OpenAI's business API — never used for model training and subject to a limited retention period of at most 30 days for abuse monitoring.
Contents
1. Privacy Architecture
Customer conversations processed by your Ragently chatbot are routed by default through the Venice AI proxy. Venice acts as an intermediate layer protecting your customer data: message content travels encrypted and is not retained by Venice.
Your customer's browser sends a message to Ragently. Ragently forwards this to the Venice proxy, which relays the request encrypted to the AI models. The response follows the same encrypted path back.
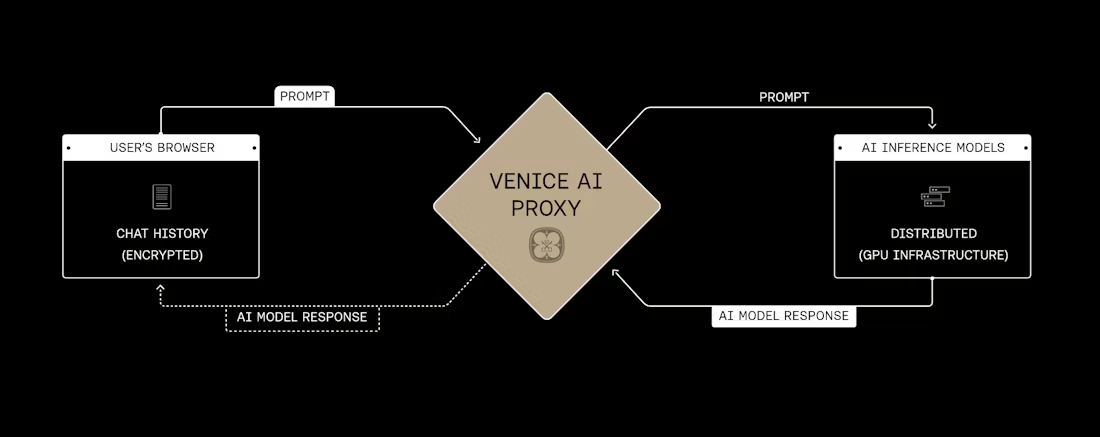
Fallback route: if Venice is temporarily unavailable, or when an image uploaded in the chat is analyzed, the request is processed by OpenAI's business API. OpenAI does not use API data for model training and retains it for at most 30 days for abuse monitoring. See also sections 7 and 8 of our privacy policy.
The Venice proxy is the shared foundation for every privacy mode. The mode of the selected model determines what happens next at the provider or model runtime layer.
2. Privacy Modes
Four modes build on the same proxy foundation — from obscuring identity to end-to-end encryption inside a verified enclave. The meter shows increasing protection.
Anonymous
Identity obscured from provider
Venice proxies the request without sending your Venice identity to the model provider. Prompt content is still visible to that provider.
Private
Zero data retention, contract-enforced
Prompt and response content is processed for inference only and is not retained after the request completes. This is the default mode for Ragently chatbots.
TEE
Hardware-isolated inference
Supported models run inside a Trusted Execution Environment with remote attestation support.
E2EE
End-to-end encrypted to a verified TEE
Your client encrypts the prompt before sending it. Venice relays ciphertext only; the verified TEE alone decrypts it.
Increasing protection: Anonymous → Private → TEE → E2EE.
3. What Ragently Stores
The best way to achieve privacy is to avoid collecting the information in the first place. Ragently stores conversation content for the inbox chat history and shares prompt and response content with AI providers solely to generate the response — never for training or permanent storage.
Not stored by AI provider
- Customer prompt content
- AI model responses
- Customer identities
- Conversation history at the provider
Operational metadata (Ragently)
- Account IDs and timestamps
- Token counts and billing data
- Selected model and endpoint
- Rate-limit state
Operational metadata: needed for authentication, billing, abuse prevention, reliability, and analytics. This is fully separate from actual prompt and response content.
4. TEE and E2EE
TEE and E2EE models add cryptographic and hardware-backed controls on top of Venice's default no-content-retention approach.
Use TEE when
you want the model to run inside an attested hardware enclave, but your client can send plaintext prompts over the normal API request.
Use E2EE when
you want prompts encrypted before they leave your client and decrypted only inside a verified TEE.
Note: E2EE disables features that need plaintext outside the enclave, such as web search, memory, summaries, and certain tool flows.
5. More about Venice AI
Ragently uses Venice AI as its AI inference provider. The full technical documentation on their privacy architecture, TEE attestation, and E2EE implementation is available on the Venice platform.
Questions about AI privacy?
We're happy to answer any questions about how Ragently protects customer conversations.
Get in touch